STUUBZZZ
MiniMax H3 RefMods vs reference images: which keeps the same face in long videos
 Watch the video · I Tested MiniMax H3 RefMods vs Reference Images for Long Videos
A RefMod from 8 pictures lifted MiniMax H3's face match from 0.23 to 0.80 in First/Last Frame mode. In a long video's second chunk, a 0.5 MP RefMod scored 0.75 against 0.25 without one. In Reference mode, one good cast picture matched it at 0.77 and rendered faster. Tested in Hybrid on an RTX 5090: one character, 3 seeds, 2026-10-24.
- In First/Last Frame mode, a MiniMax H3 RefMod from 8 pictures at 1 MP scored a face match of 0.80 against 0.23 for words alone, in a scene none of the pictures show (6-second Hybrid chunk, one character, 3 seeds, RTX 5090, Ultimate H3 0.14, 2026-10-24). The character's own footage scores 0.85.
- In a 12-second MiniMax H3 video in two chunks (First/Last Frame, Hybrid, 3 seeds, RTX 5090, 2026-10-24), every seed's second chunk scored 0.66 to 0.80 with a RefMod at 0.5 MP and 0.16 to 0.33 with words alone.
- In MiniMax H3's Reference mode, one design picture in the cast did as well as a RefMod at 0.5 MP: 0.77 each in one chunk, 0.74 against 0.76 in chunk 2 of 12 seconds, which took 140 s against 167 s to render (RTX 5090, 3 seeds, 2026-10-24).
- A RefMod of eight pictures slowed MiniMax H3 on an RTX 5090 (medians, 2026-10-24): Hybrid about 15% at 0.5 MP and 28 to 33% at 1 MP, PDMD 13% at 1 MP.
What is a MiniMax H3 RefMod?
A MiniMax H3 RefMod is a set of pictures of one character, encoded once with H3's own video VAE and saved as one small .safetensors file. RefMods come from Luisacaotica's ComfyUI-MiniMaxH3Mod (MIT), and my pack uses the same file format.
When you render, the pictures go in through H3's own reference path, the one a reference picture takes. You load the file like a LoRA, but nothing gets trained. For the trained route, see training a MiniMax H3 character LoRA; I did not compare them.
H3's text encoder never sees these pictures. The pictures carry the face, so the words still have to say who the character is.
The terms this post uses:
- MiniMax H3 is MiniMax's open video model with sound: it generates the picture and the audio in the same pass.
- First/Last Frame mode is the Ultimate H3 mode that takes zero, one or two frame images plus your words. It has no cast.
- Reference mode, Reference (Omni) in the Director, takes up to 9 images, 3 videos and 3 audio clips. Pictures of your characters go in its cast.
- PDMD and Hybrid are mode presets on Ultimate H3's Setup node, separate from the two modes above: PDMD renders in 4 steps with its own LoRA, Hybrid in 10 with the turbo LoRA.
- A chunk is one MiniMax H3 generation. A long video renders chunk by chunk, and each chunk after the first starts from the one before it, unless it cuts to a new shot.
How long does it take to make a RefMod?
A few seconds: my three Make runs in Stubelius Ultimate H3 took 2.2 to 3.0 seconds on an RTX 5090 (0.14), for a 0.74 MB file at 0.5 MP, and Make waits for any render in progress. The slow part is the pictures.
Mine came from Qwen-Image 2.1 by Qwen: a design still, then edits, 13 pictures (8 for the RefMod) in 492 seconds.
How do I make a RefMod in Stubelius Ultimate H3?
Open the Characters lane in the Director, click +, choose Make a character from pictures, drop in 8 to 16 pictures, describe the character and click Make. Characters have been in Stubelius Ultimate H3, my free custom node pack, since 0.13. It is at 0.15.1 on GitHub main; my captures and tests ran on 0.14.
Charactersis the timeline's last row:+→Make a character from pictures.- Drop the pictures in and name it. The dialog shows the cost: about 3.9k tokens in every sampling step for 8 pictures.
- Pick
0.5 MP(the default) or1 MP, and underIn wordsdescribe it, short and specific. - Click
Make. The file and a contact sheet land in ComfyUI-MiniMaxH3Mod'srefmodsfolder when that pack is installed, otherwisemodels/refmods(model folders). - Click the character on the lane, then
Add it to chunk 1's first shot, which types the description into that shot.
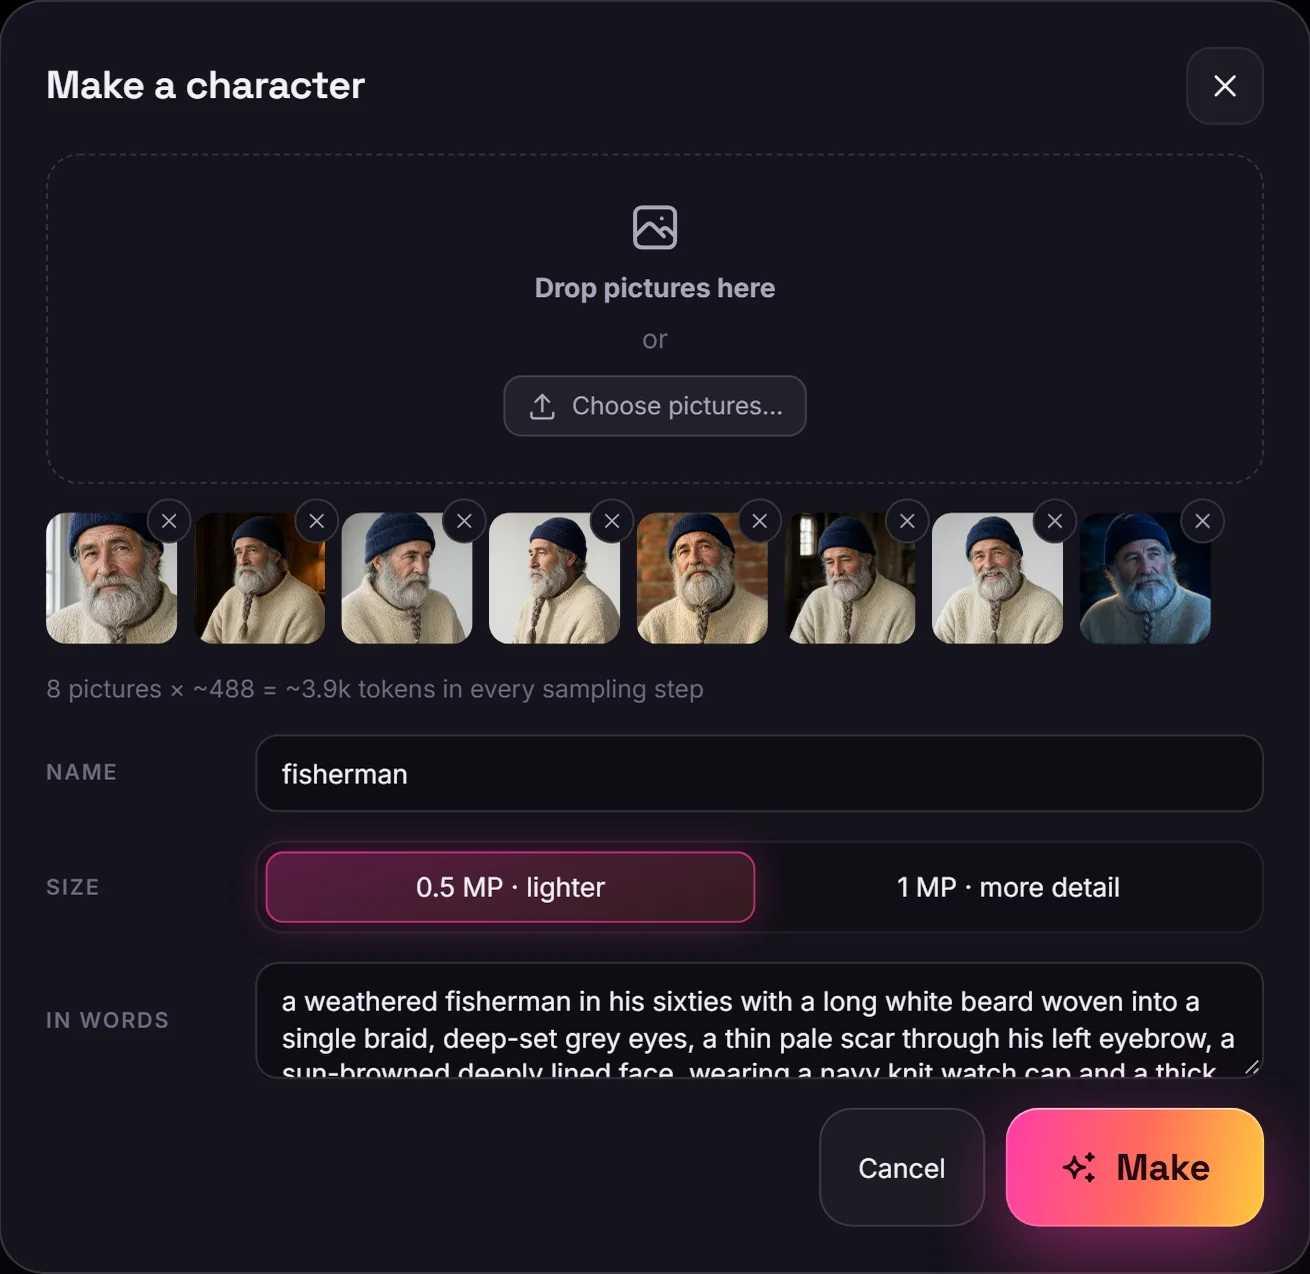
Next time it's + → Add a saved character. RefMods made with Luisacaotica's pack load here, and the other way round. Fizgig by shootthesound makes tuned ones that load too, but use them in the mode they were tuned for. Below 100%, Strength blurs the pictures for a looser likeness; every test here ran at 100%.
Which pictures make a good RefMod?
Use 8 to 16 pictures of one character, face and shoulders, from different angles and in different light, with nothing else in focus. ComfyUI-MiniMaxH3Mod's README warns that clothing, background and composition can mix in with the identity. My set was 8 pictures, four of them close-ups.
- One shape: the first picture sets it, and a picture of another shape gets its middle cut out.
- Character sheets: cut a sheet into separate views, or each face ends up tiny. My character dataset guide covers the views.
- Unusual looks: say them in words too, such as paper-white skin. H3 likes to pull an unusual look back toward normal.
Does a RefMod keep the same face?
Yes, in my 2026-10-24 test: with 8 pictures of a fisherman, a 6-second Hybrid chunk scored 0.80 in First/Last Frame mode and 0.77 in Reference mode, against 0.23 and 0.34 for words alone. His own footage scores 0.85. Three seeds per row, one character, one scene.
| Mode and what H3 got | Face match | Score on seeds 101 / 202 / 303 | Render time (median, seconds) |
|---|---|---|---|
| First/Last Frame, words only | 0.23 | 0.20 / 0.21 / 0.28 | 48.3 |
| First/Last Frame, RefMod (1 MP) | 0.80 | 0.83 / 0.76 / 0.81 | 64.1 |
| Reference, words only | 0.34 | 0.34 / 0.37 / 0.31 | 50.0 |
| Reference, one design picture in the cast | 0.77 | 0.82 / 0.69 / 0.80 | 48.5 |
| Reference, RefMod (0.5 MP) | 0.77 | 0.83 / 0.68 / 0.80 | 57.1 |
| Reference, RefMod (1 MP) | 0.76 | 0.82 / 0.63 / 0.82 | 63.9 |
| Reference, design picture + RefMod (1 MP) | 0.73 | 0.83 / 0.55 / 0.80 | 66.3 |
| Reference, one of the 8 pictures alone in the cast | 0.69 | 0.75 / 0.56 / 0.76 | 43.9 |
Tested 2026-10-24 on an RTX 5090 (32 GB), 96 GB RAM, Windows 11, Ultimate H3 0.14. Hybrid: 10 steps, 0.5 megapixels, turbo LoRA at 0.75. Face match is face recognition (InsightFace ArcFace) against other footage of him: each take's median over its frames, averaged over the seeds.
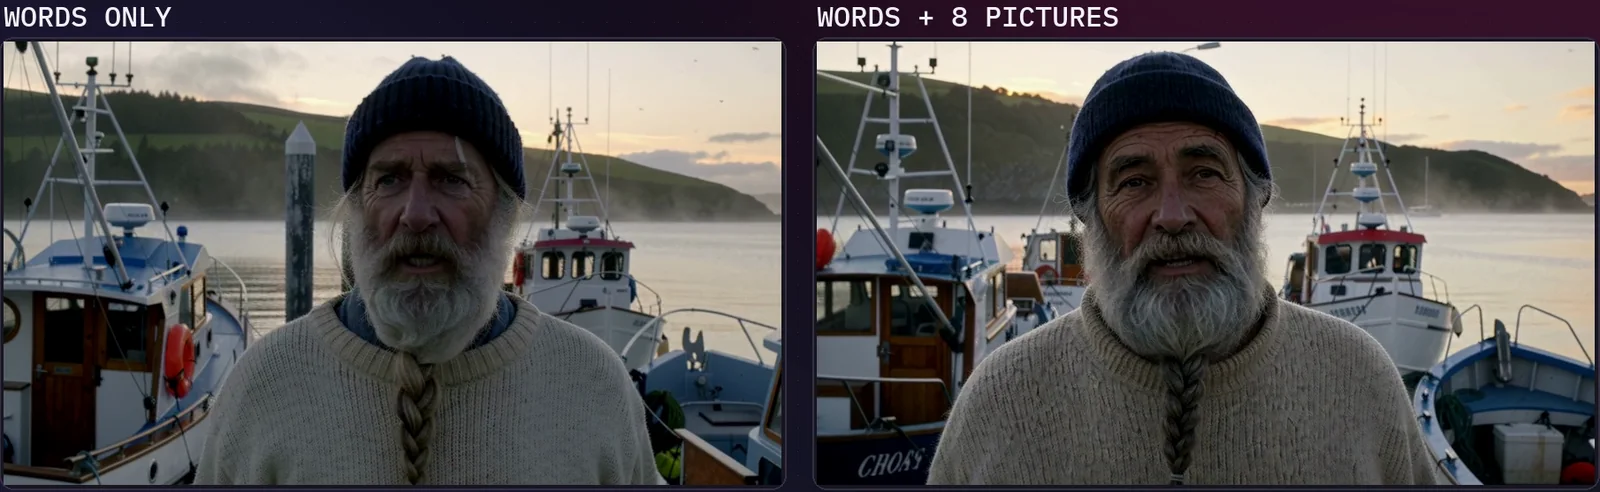
Seed 202 was the weakest in every Reference row with pictures, so read gaps of a few hundredths as a tie. Dialogue held too: Whisper heard the spoken line word for word in all 30 takes with a RefMod and in 23 of 24 without.
Does a MiniMax H3 RefMod hold the face across chunks of a long video?
Yes, on my three seeds. In First/Last Frame mode, 12 seconds in two Hybrid chunks, the second chunk scored 0.75 with a RefMod at 0.5 MP against 0.25 for words alone. The description was in chunk 1 only, and chunk 2 just says "he".
PDMD mode (4 steps, the LoRA by Zimo Wang et al.) showed the same with a RefMod at 1 MP, 0.76 against 0.27.
| Mode and what H3 got | Chunk 1 | Chunk 2 | Chunk 2, lowest to highest seed | Render time (median, seconds) |
|---|---|---|---|---|
| Hybrid, words only | 0.25 | 0.25 | 0.16 to 0.33 | 113 |
| Hybrid, RefMod (0.5 MP) | 0.81 | 0.75 | 0.66 to 0.80 | 130 |
| Hybrid, RefMod (1 MP) | 0.77 | 0.70 | 0.58 to 0.80 | 149 |
| PDMD, words only | 0.28 | 0.27 | 0.20 to 0.31 | 145 |
| PDMD, RefMod (1 MP) | 0.77 | 0.76 | 0.70 to 0.80 | 164 |
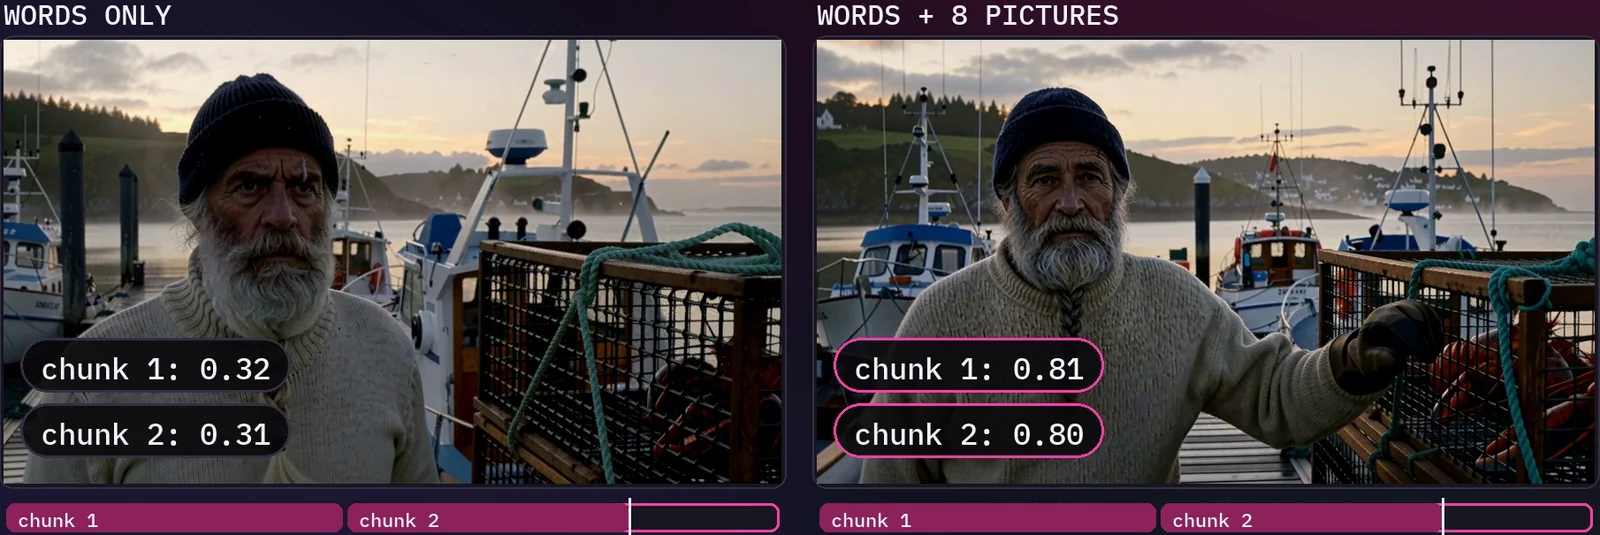
At 18 seconds in three Hybrid chunks, words alone scored 0.25, 0.25 and 0.23, and the RefMod at 0.5 MP 0.81, 0.75 and 0.75. It doesn't stop every drift: seed 303 went 0.80, 0.66, 0.61.
Which is better in MiniMax H3 Reference mode, a RefMod or a reference image?
Neither, on my 2026-10-24 test: one good design picture in the cast matched the RefMod, 0.77 each in one chunk and 0.74 against 0.76 in chunk 2, and the RefMod took about 20% longer to render. Both together didn't add anything. That's one character over three seeds; my two earlier tests, below, scored one picture lower than the RefMod.
| What H3 got | Chunk 1 | Chunk 2 | Render time (median, seconds) |
|---|---|---|---|
| One design picture in the cast | 0.74 | 0.74 | 140 |
| RefMod | 0.76 | 0.76 | 167 |
| Design picture + RefMod | 0.67 | 0.74 | 180 |
In this Hybrid test on 0.14, the cast goes into chunk 1 only and a RefMod into every chunk. But chunk 2 continues from chunk 1's frames, and those carried his face along.
- A reference image wins in Reference mode when you have one good picture: no Make step and no added render time. The first cast picture is also
<Subject 1>if you want to point at him in a shot. - A RefMod wins in First/Last Frame mode, where there is no cast, and keyframes, middle frames and sounds stay as they are. It also beat a weaker single picture: one of the 8 alone scored 0.69, against 0.77 for the RefMod and for the design picture.
Why did my earlier RefMod test show 0.74 against 0.40?
Because it was another character in a separate test: the 2026-10-15 test in my long-videos post scored 0.74 against 0.40, and the 2026-10-24 test on a new character scored 0.80 against 0.23. The direction held. Each test has its own scale, so compare within a row, not across rows.
| Test | The character's own footage or portraits | Reference: words only | Reference: one picture | Reference: RefMod (0.5 MP) | Reference: picture + RefMod (1 MP; 10-21: 0.5 MP) | First/Last Frame: words only | First/Last Frame: RefMod (1 MP) |
|---|---|---|---|---|---|---|---|
| 2026-10-24, 8 pictures, 3 seeds | 0.85 | 0.34 | 0.77 | 0.77 | 0.73 | 0.23 | 0.80 |
| 2026-10-15, 8 pictures, 3 seeds | 0.74 | 0.35 | 0.51 | 0.66 | 0.72 | 0.40 | 0.74 |
| 2026-10-21, 7 pictures, 1 seed | 0.96 | 0.26 | 0.44 | 0.55 | 0.55 | – | – |
Three different characters, none tested on 0.15.1: 10-24 on Ultimate H3 0.14, 10-15 on 0.13 test builds. The 10-15 row is from the pack's README before its 10-24 update. The 10-21 clips ran 6.6 seconds, scored against the mean of her 9 portraits, not footage; her own score is those portraits against that mean.
These results changed two lines in my older post. It used to advise pairing a cast picture with a character in Reference mode, from the 10-15 test, where the pair scored highest; on 10-24 it added nothing. It also gave a cost of about 4 seconds per chunk at 0.5 MP, from means that included a warm-up run; the medians below are 7 to 8.
How much render time does a RefMod cost?
About 15% at 0.5 MP in Hybrid (7 to 8 seconds per 6-second chunk), 28 to 33% at 1 MP (14 to 18 seconds), and 13% in PDMD at 1 MP (medians on an RTX 5090, 2026-10-24). 0.5 MP is the default.
0.5 MP held the face as well as 1 MP, and scored higher in the second Hybrid chunk in First/Last Frame mode, 0.75 against 0.70. Each picture adds reference tokens to every sampling step, about 500 at 0.5 MP and 1,000 at 1 MP. The Director's footer shows your total.
Can a RefMod hold a character's voice?
The file can, but Ultimate H3's Characters lane uses only the pictures. ComfyUI-MiniMaxH3Mod makes audio RefMods too, and its README lists voice transfer as a known failure. For a voice, use a reference audio sample in Reference mode, or Lip Sync with the exact recording for every chunk.
What are the limits of this test?
The 2026-10-24 test covers one character in one scene, on three seeds per row and one card, so read the scores as one test, not a rule (how I test).
- The 2026-10-24 tests: one live-action character, one scene, one render per seed, three seeds per row, one RTX 5090.
- His pictures and his own footage (4 clips rendered by H3, PDMD) come from the same Qwen-Image 2.1 design still. The score says how close a take is to that footage, not whether a shot looks good.
- A score covers only frames with a face found: 58 to 100% in the one-chunk Reference takes, 100% in First/Last Frame.
- The 18-second runs reused chunks 1 and 2 of the 12-second runs as kept takes, so only chunk 3 is new, and I quote no render time for them. The spoken line is in chunk 2, so 3 takes in each dialogue count are repeats.
- The 2026-10-24 tests ran on Ultimate H3 0.14, not repeated on 0.15.1 or in FastH3 Omni or Pika H3 Flex mode.
- Not tested: two characters in one shot, 2D and anime faces, a
New shotjoin, more than 8 pictures, strength below 100%, VRAM use, other cards, a trained LoRA.
Sources and files
- I Tested MiniMax H3 RefMods vs Reference Images for Long Videos: the tests at 1:41, making one at 4:53, ref image vs RefMod at 7:13 and long videos at 8:11.
- Claude Code by Anthropic made this video: it ran the tests, narration and edit, and the calls made by eye and ear stayed mine. See how Claude Code made this video.
- ComfyUI-MiniMaxH3Mod by Luisacaotica (MIT), and stuubszzz/Stubelius-Ultimate-H3, my free pack (MIT), whose README has the 2026-10-24 numbers.
- The MiniMax H3 model card and the PDMD 4-step LoRA.
- On this site: long videos and retakes, FastH3 Omni vs PDMD and the free Part 1 of ComfyUI From Zero.
Common questions
Are MiniMax H3 RefMods free?
Yes. ComfyUI-MiniMaxH3Mod and Stubelius Ultimate H3 are both MIT licensed and free on GitHub. The MiniMax H3 model is a separate download under the MiniMax H3 Community License: read it before commercial use.
Should I make a RefMod or train a LoRA?
Try a RefMod first, on cost alone: once you have the pictures, Make takes about 3 seconds, against about 15 GPU hours for my trained character LoRA on an RTX 5090. I didn't compare their likeness, so this says nothing about which holds a face better.
Does a MiniMax H3 RefMod need more VRAM?
Not measured: I logged no VRAM figure for it on my RTX 5090 (32 GB). A separate test saw a whole-card peak of 30.4 GB for H3 in PDMD mode on that card, which isn't a minimum. With less VRAM, the pack's README points to the low-VRAM switches in Setup, or GGUF models.
Should a RefMod be 0.5 MP or 1 MP?
0.5 MP, the default. It scored 0.77 against 0.76 at 1 MP in one Reference chunk and 0.75 against 0.70 in chunk 2 in First/Last Frame mode, with about half the added render time (three seeds, 2026-10-24).
Do I need to tag a RefMod in the prompt?
No. In Ultimate H3 the character on the lane needs no at sign or Subject number in either mode, but the words must still describe it.
Does a RefMod work for anime characters or two people in one shot?
Unmeasured. Face recognition can't score 2D faces, and I haven't tested two characters in one shot. To try it yourself, render the same seed and words with and without the RefMod and compare them by eye; that's a suggestion, not a result.