STUUBZZZ
FastH3 vs Turbo LoRA on MiniMax H3: 5.1 vs 6.21 minutes per clip on an RTX 5090
 Watch the video · Is Minimax FastH3 worth the hype?
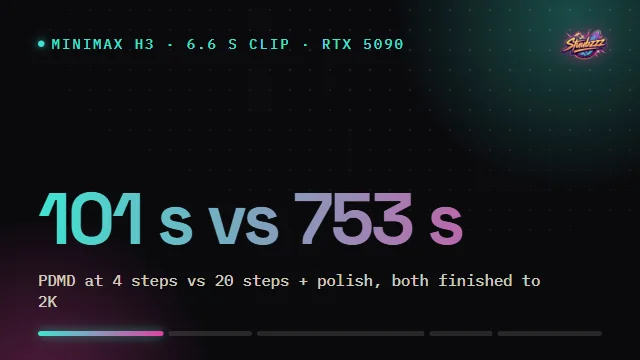
On an RTX 5090, the FastH3 preview adapter at 6 steps finished a 15-second, 720p MiniMax H3 reference-to-video clip in 5.1 minutes. The 8-step Turbo LoRA needed 6.21 minutes for the same clip, so the FastH3 run took about 18% less time. A step took about 6 seconds with either LoRA, so the adapter did not make steps faster. It let the run use fewer of them.
- On an RTX 5090 (32 GB), a 15-second, 720p MiniMax H3 reference-to-video clip took 5.1 minutes with the FastH3 Preview v1 adapter at 6 steps and 6.21 minutes with the 8-step Turbo LoRA, about 18% less time. One clip per setting.
- Time per sampling step on the RTX 5090 was 5.9 to 6.2 seconds with the converted FastH3 adapter and 6.1 to 6.4 seconds with the 8-step Turbo LoRA, on one MiniMax H3 clip each. The ranges overlap, so I treat the cost of a step as the same.
- FastVideo publishes the FastH3 Preview v1 adapter as a 4-step LoRA, but the README of the ComfyUI converter I used recommends 6 steps for the converted file. I ran 6 in total, 3 of them in the Seed Hunt pass.
- FastVideo's figure of up to 14× is measured against base MiniMax H3 at 49 transformer calls, on an NVIDIA B200 with its sparse-attention checkpoint. It is not a comparison with an 8-step Turbo LoRA on an RTX 5090.
- As of 30 September 2026, ComfyUI's official FastH3 templates use a separate 8-step V2 checkpoint for text-to-video and image-to-video. This test covers only the 4-step Preview v1 adapter, on reference-to-video.
Update, 30 September 2026. This test covers the FastH3 4-step Preview v1 adapter, loaded as a LoRA. The official ComfyUI docs now have a FastVideo FastH3 page with two native templates, text to video and image to video. They use a separate 8-step V2 checkpoint, repacked by Comfy-Org as fastvideo_fasth3_8step_v2_pruned_int8_convrot.safetensors (about 22 GB), need ComfyUI 0.36.0 or later, and keep the step count fixed at 8. According to the docs, that checkpoint covers text-to-video and first/last-frame image-to-video only, and reference-to-video was not distilled. I have not re-tested with that release, so every number below belongs to the preview adapter.
Test setup
- MiniMax H3 reference-to-video, 16:9, one 15-second clip per setting.
- Workflow: Stubelius Director, my fork of Muse Collective's MiniMax H3 Director V1.2. Seed Hunt and the Refine node come from their pack.
- Seed Hunt at 0.25 megapixels, then a 2× upscale in the refine pass to 1344×768, which the video and this post loosely call 720p.
- Run A: the 8-step Turbo LoRA at 8 steps.
- Run B: the FastH3 Preview v1 adapter, converted for ComfyUI, at 6 steps in total with 3 in the Seed Hunt. The Refine node was set to the same 6 and 3.
- Both runs used these resolution settings, with the LoRA and the step counts swapped. I did not note the seeds or the number of Seed Hunt candidates.
How much faster is FastH3 than the 8-step Turbo LoRA?
About 18% less time on one clip: 5.1 minutes with the FastH3 adapter at 6 steps, against 6.21 minutes with the Turbo LoRA at 8, with about the same time per step.
| Measure | Turbo LoRA, 8 steps | FastH3 adapter, 6 steps |
|---|---|---|
| Steps | 8 | 6 (3 in the Seed Hunt) |
| Iteration time | 6.1 to 6.4 s/it | 5.9 to 6.2 s/it |
| Total clip time | 6.21 min | 5.1 min |
| Look, by eye | Slightly more convincing motion | Close to identical to the Turbo clip |
Tested 2026-09-02 on an RTX 5090 (32 GB), 96 GB RAM, Windows 11. One 15-second clip per setting, so treat each figure as a single sample.
The two iteration-time ranges overlap, so the adapter does not make a step cheaper when it is loaded as a LoRA in ComfyUI. What it changes is how many steps the run needs. That adds up when you scout seeds, because every candidate costs fewer steps.
The totals cover the whole run, and I did not time the passes separately. Two steps at about 6 seconds are roughly 12 seconds, and the gap between the runs was a little over a minute. The run has more than one sampling pass, the low-resolution hunt and then the Refine node at the higher resolution, and I noted one iteration-time range per LoRA, not one per pass. Read 18% as the result for this clip and this setup, not as a figure derived from the step count.
The quality call is mine, from one pair of clips: close to identical, with marginally more convincing motion in the Turbo LoRA run.
Why 6 steps if FastH3 is a 4-step adapter?
Because the converter's README recommends 6 for the converted file in ComfyUI. FastVideo distilled the adapter for 4 steps in its own runtime, and in ComfyUI the converted file needs more. The README of the converter I used describes 4 steps as jitter, flicker and colour bloom, 5 as fine for drafts, 6 as the recommended setting and 7 to 8 as marginal gains.
The reason given there is structural. The adapter's AdaLN weights, which handle timestep modulation, do not fit the reduced layers in ComfyUI's pruned H3 checkpoint. The converter drops them, and the extra steps make up for it.
If you scout with the Director and finish in the Refine node, give Refine the same total and first-pass step counts, because it continues the candidate's schedule from where the scout stopped. With sync_from_director on, the default in the public pack, Refine reads both from the candidate.
Which one should you run?
- Speed first, simple motion: run the whole clip on the FastH3 adapter at 6 steps. It took about 18% less time here and I could barely tell the results apart.
- Motion is the point of the shot: the 8-step Turbo LoRA had a slight edge in motion in my one comparison.
- Complex action, high detail: scout the seeds with FastH3 switched on, then switch the LoRA off in the Refine node and finish on the full model. With a 20-step Director schedule and 3 steps spent in the hunt, that leaves 17 for the refine, followed by a 6 to 16 step polish. This is the split I recommend in the video. I did not time it in this test.
One caveat applies to all three. FastVideo's model card describes the preview adapter as text-to-audio-video, and I ran it on the reference-to-video checkpoint. It held up on this clip, which is one data point and not a guarantee.
Why the adapter and not a full FastH3 checkpoint?
Because of size: the converted adapter is a LoRA of about 1 GB, and when I ran this test the full FastH3 preview checkpoints were replacement transformers of about 66 GB. On a 5090 with 96 GB of system RAM that was too heavy once a large text encoder and a LoRA stack were loaded, and I did not want to quantise a preview that was still changing. So the adapter is what I measured.
I made the LoRA with NikoDemon80's FastH3 LoRA converter for ComfyUI, from the dense-datafree adapter in FastVideo's repository. The details are in my post on how to load the FastH3 adapter in ComfyUI and why the unconverted file does nothing. When the video went up I put the converted 6-step LoRA on Patreon as a free download.
Sources and files
- FastVideo FastH3 4-step Preview v1 LoRA, the adapter model card. My LoRA was converted from
dense-datafree/adapter_model.safetensors. - FastVideo FastH3: ComfyUI workflow examples, the official docs for the 8-step V2 templates, and FastVideo-FastH3-Comfy, the repacked checkpoint.
- FastVideo on GitHub. The 14× figure and the 49-call baseline come from the team's FastH3 Preview v1 announcement of 27 August 2026, which the ComfyUI docs page links to.
- MiniMax H3, the base model card.
- ComfyUI-FastH3-Lora-Converter by NikoDemon80, the converter and its step-count notes.
- Stubelius Director, the nodes used for the test, a fork of MiniMaxH3-Director-V1.2 by Muse Collective.
- Is Minimax FastH3 worth the hype?, the video with both clips side by side.
- On this site: converting the FastH3 adapter for ComfyUI and the Director, Seed Hunt and two-stage sampling. In ComfyUI From Zero, Part 2 covers the steps and CFG a speed LoRA needs.
Common questions
Is FastH3 really 14× faster in ComfyUI?
Not in this test. FastVideo reports 14.38× for a 15-second clip on one NVIDIA B200, using its sparse-attention checkpoint against base MiniMax H3, which calls the transformer 49 times. I compared the dense preview adapter at 6 steps with an 8-step Turbo LoRA on an RTX 5090, and the clip time went from 6.21 to 5.1 minutes, about 18% less.
Should I run the FastH3 adapter at 4 steps?
Not the converted adapter in ComfyUI. The converter's README reports jitter, flicker and colour bloom at 4 steps and recommends 6. I used 6 steps in total with 3 in the Seed Hunt, and set the Refine node to the same two numbers.
Does this test cover the 8-step FastH3 V2 checkpoint?
No. It covers the 4-step Preview v1 adapter, tested on 2 September 2026. The 8-step V2 checkpoint in ComfyUI's official templates is a separate release for text-to-video and first/last-frame image-to-video, and I have not timed it.