STUUBZZZ
MiniMax H3 2.5D anime style LoRA: what the retrain changed and which strength to use
 Watch the video · I Tried Minimax H3 2.5D: Here Is The Truth
MiniMax H3 prompted for 2.5D anime tends to land on flat 2D or slide toward 3D, and a rank-16 style LoRA holds the glossy look in between. The retrained version (v2.0, published 2026-09-30) was trained on 50 three-second captioned clips, and in a same-seed sweep of that training run strength 0.8 kept the reference image's framing while 1.0 began to re-stage the shot.
- MiniMax H3 asked for "2.5D anime" in the prompt tends to return flat 2D anime or drift toward 3D realism. A style LoRA trained on clips in the target look holds the middle.
- The retrained 2.5D style LoRA for MiniMax H3 (v2.0, published 2026-09-30) is rank 16, trained for 3,500 steps on 50 three-second captioned clips at 256 and 512 px with audio, for the reference-to-video (Ref2VA) checkpoint. The trigger word is
2.5D. - In a same-seed strength sweep on three reference images (RTX 5090, 32 GB, one seed per setting, run on a later save of the training run behind v2.0), every strength from 0.4 to 1.0 completed the prompted action, gloss rose with strength, 0.8 kept the reference framing in all three scenes and 1.0 re-staged two of them.
- The published v2.0 file at strength 1.0, on the same three references and seed (RTX 5090, 32 GB), completed every action with no artifacts and kept the high-angle framing of the snow scene.
Updated 2026-09-30. This post first covered only version 1.0, which is also what the video shows. It now adds the retrained version and a strength sweep, and corrects one detail: both versions were trained on short video clips, not on stills.
Why does MiniMax H3 fall back to flat anime or 3D?
H3 has a strong default for anime, and it is a flat 2D look. Adding words such as "high fidelity, semi-realistic, 2.5D anime, 2.5D animation" did not get me the look I had in mind. When a clip did leave 2D, it leaned toward 3D realism: less detail in the face, toned-down colours, clothes that look glued on.
I tried different reference images, several references at once and different characters. By my rough estimate about 70% of those attempts came out 2D. That is a number from memory, not a benchmark, but it was enough to stop prompting and train a LoRA.
The target look came from stills made with a community finetune of Illustrious XL plus a third-party style LoRA at about 0.75 strength: glossy, smooth, high-fidelity rendering.
Version 1.0: what the video shows
The 2.5D video covers the first version only. It compares one reference image with and without the LoRA, on the H3 reference-to-video model with a turbo LoRA in the stack:
- Without the LoRA: the face and small details such as jewellery lose definition, colours are toned down and the clip leans toward 3D realism.
- With the LoRA: the skin gloss is there, hair, eyes and small details stay clear, and the motion reads smoother.
I also tried FastH3. For this style I preferred the result with the turbo LoRA, so the examples use it. How the two compare on render time is in the FastH3 speed test.
What changed in the retrained version?
Version 2.0 is a full retrain on a new set. I made 50 stills in the target look and animated each into a three-second clip with MiniMax H3. Every clip has a caption file that starts with the trigger word. 35 clips are widescreen and 15 are portrait. The listing gives the aim as better movement and camera angles.
| Setting | Version 1.0 | Version 2.0 (retrained) |
|---|---|---|
| Published | 2026-09-09 | 2026-09-30 |
| File | 2k_2.5d_Minimax_ref.safetensors | H3_R16_2.5d_style_v2_000003500.safetensors |
| Training clips | 48 | 50, three seconds each |
| Resolution settings | 256 px | 256 and 512 px |
| Steps in the published save | 2,000 | 3,500 |
| Rank / alpha | 16 / 16 | 16 / 16 |
| Audio trained | Yes | Yes |
| Trigger word | 2.5d | 2.5D |
| Target model | H3 Ref2VA | H3 Ref2VA |
Both were trained in AI Toolkit at learning rate 1e-4. Version 1.0 used Contrastive Guidance + Training Adapter, the toolkit's default at the time, and version 2.0 used the Training Adapter alone with the newer adapter file. What those options do is in the distillation handling post. I ran version 1.0 to 4,000 steps, found that overbaked, and published the 2,000-step save.
Both files are listed on Civitai.
Which LoRA strength should you use?
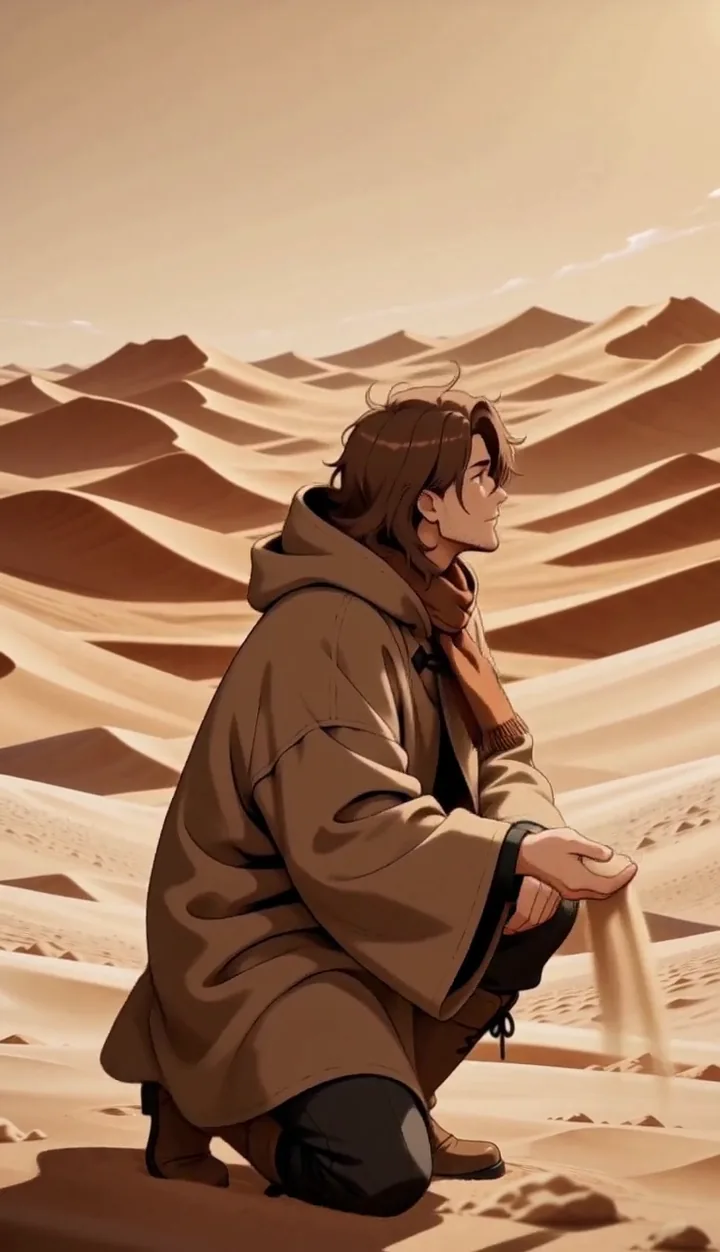
Start at 0.8 if the framing of your reference image matters, and at 1.0 if you want the full look. I rendered three reference images with the retrained LoRA at 0.4, 0.6, 0.8 and 1.0, with seed and prompt fixed per image, so strength is the only variable.
| Strength | Look | Reference framing and lighting |
|---|---|---|
| 0.4 | Brightest and flattest shading of the four | Kept in all three scenes |
| 0.6 | Between 0.4 and 0.8 | Kept in all three scenes |
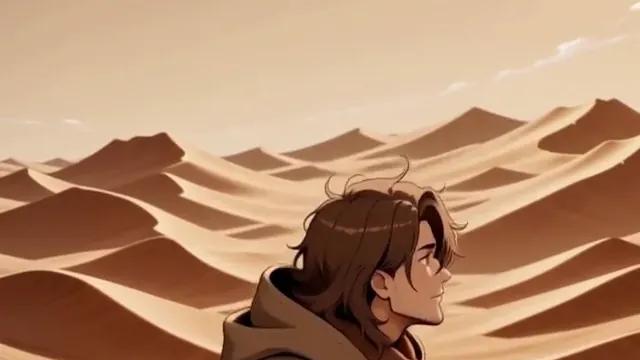
| 0.8 | Most of the gloss | Framing kept in all three. In the desert scene the large white sun became a lens-flare ray |
| 1.0 | Deepest shading, glossiest hair highlights, face a little more defined | Desert: sun gone, tighter framing, more contrast. Snow: camera moved from a high angle to eye level, with a new night sky and a stronger push-in. Flower shop: composition unchanged |
Two things did not get worse with strength. Every strength performed the whole prompted action, and render time did not rise: 101 to 161 s per clip across the ten clean timings, with the three clips at 1.0 taking 101 to 110 s.
The published 2.0 file, rendered at 1.0 on the same three references and seed, completed every action with no artifacts, and it kept the high-angle framing in the snow scene. On that evidence it re-stages less at 1.0 than the table shows, but that is one scene.
Tested 2026-09-29 on an RTX 5090 (32 GB), 96 GB RAM, Windows 11, in the Stubelius Ultimate H3 workflow: MiniMax H3 Ref2VA, Hybrid mode (10 steps) with an 8-step turbo LoRA at 0.75, megapixels raised from the preset's 0.5 to 0.9 (736×1280), 124 frames at 24 fps, no upscaling. One seed per setting (seed 42 for every clip). The four-strength sweep ran on a later save of the same training run, not on the published 2.0 file, so read it as a tendency of this training. The three reference images are stills that training clips were animated from, so the LoRA had seen these characters. The prompted actions were new. Two clips slowed by VRAM contention (361 s and 1,863 s) are left out of the timing range.
How to use it
- Put the
.safetensorsfile inComfyUI/models/lorasand refresh ComfyUI. - Load the MiniMax H3 Ref2VA checkpoint. Both versions were trained for it.
- Add the LoRA with a normal model-only LoRA loader. In Stubelius Ultimate H3, use one of the two global LoRA slots on the Models node or the per-chunk LoRA picker in the Director.
- Start the style line of your prompt with the trigger:
2.5Dfor version 2.0,2.5dfor version 1.0. - Set the strength. For version 2.0 use the sweep above. For version 1.0 my note was 1.0, with 0.7 to 1.0 as the working range.
Training your own style LoRA this way
- Generate stills in the exact look. Vary the subject and the framing, keep the rendering constant.
- Animate each still into a short clip with the video model you are training for, and caption each clip starting with your trigger word.
- Train and keep several saves. On the retrain I saved every 500 steps at first and every 250 later.
- Compare saves at strength 1.0, then sweep the strength of the one you pick, always on a fixed seed.
Part 3 of ComfyUI From Zero shows this dataset build and training run on screen. A character LoRA needs a different kind of set, covered in the character dataset post. If you want a style locked for your project without doing the training, that is a commission.
Sources and files
- AI Toolkit by Ostris: the trainer used for both versions.
- MiniMax H3 model card.
- Stubelius Ultimate H3: my free ComfyUI workflow, used for the strength sweep.
- I Tried Minimax H3 2.5D: Here Is The Truth: the video for this post. It covers version 1.0.
- AI Toolkit distillation handling for MiniMax H3 LoRAs.
- The dataset behind a consistent character LoRA.
- FastH3 vs Turbo LoRA speed test.
- ComfyUI From Zero: Part 3 shows the dataset and training run of the retrained version.
Common questions
Does a higher LoRA strength slow the render or weaken the motion?
Not in this sweep. From strength 0.4 to 1.0 every clip completed the whole prompted action, and the ten clean timings ran from 101 to 161 s per 124-frame 736×1280 clip on an RTX 5090 (32 GB), with the clips at 1.0 taking 101 to 110 s.
Does the 2.5D LoRA work with the MiniMax H3 first/last-frame model?
Both versions were trained for the reference-to-video (Ref2VA) checkpoint. Version 1.0 also worked on the first/last-frame model when I tried it. I have not tested the retrained version there, so I can only vouch for it on Ref2VA.
Why not just use a stronger prompt for 2.5D?
Because in my attempts the prompt words moved MiniMax H3 between a flat 2D look and a 3D look without settling in between. A style LoRA trained on clips in the target look held the middle on the same reference image.